The job of a (pre)seed fund is to find outlier founders who've lived the problem they're solving, and work with them on the long climb to product-market fit.
In reality, most of a VC's week goes on other things, like screening decks, sizing markets and checking what founders claim. AI now does those better than we do.
It can't read a founder, or tell when a company that doesn't look like anything before it is worth backing. That's still our job, and we wanted more time for it, so we stopped looking at new deals and handed AI the jobs it's better at.
Skip to a section
01
What happens to a dealThe seven stages a deal goes through, from the inbox to a partner's call.
5 min
02
How it's builtThe four layers, what we built and what we bought, and why the agents run in a fixed order.
How we keep it honestLogging every run, testing every change, and which models we use and when we change them.
5 min
05
What it can’t do yetThe deals it will always miss, how it learns from every deal, and why we’ll rebuild it.
3 min
What happens to a deal
Every deal goes through the same seven stages in the same order. See the flow →
1. Whichever way it comes in, we read it the same way
A deal can arrive through the pitch form on our website, a chatbot founders can pitch to instead, an email address founders send decks to, a post in the Slack channel where the team shares deals, a referral from someone in our network, or Sourcing Signals, an agent that finds founders before they apply. Each route has its own ingestor, an n8n workflow that turns whatever arrives into one standard record every later step reads, with missing fields marked as missing, never dropped. No two steps ever work from different versions of the facts.
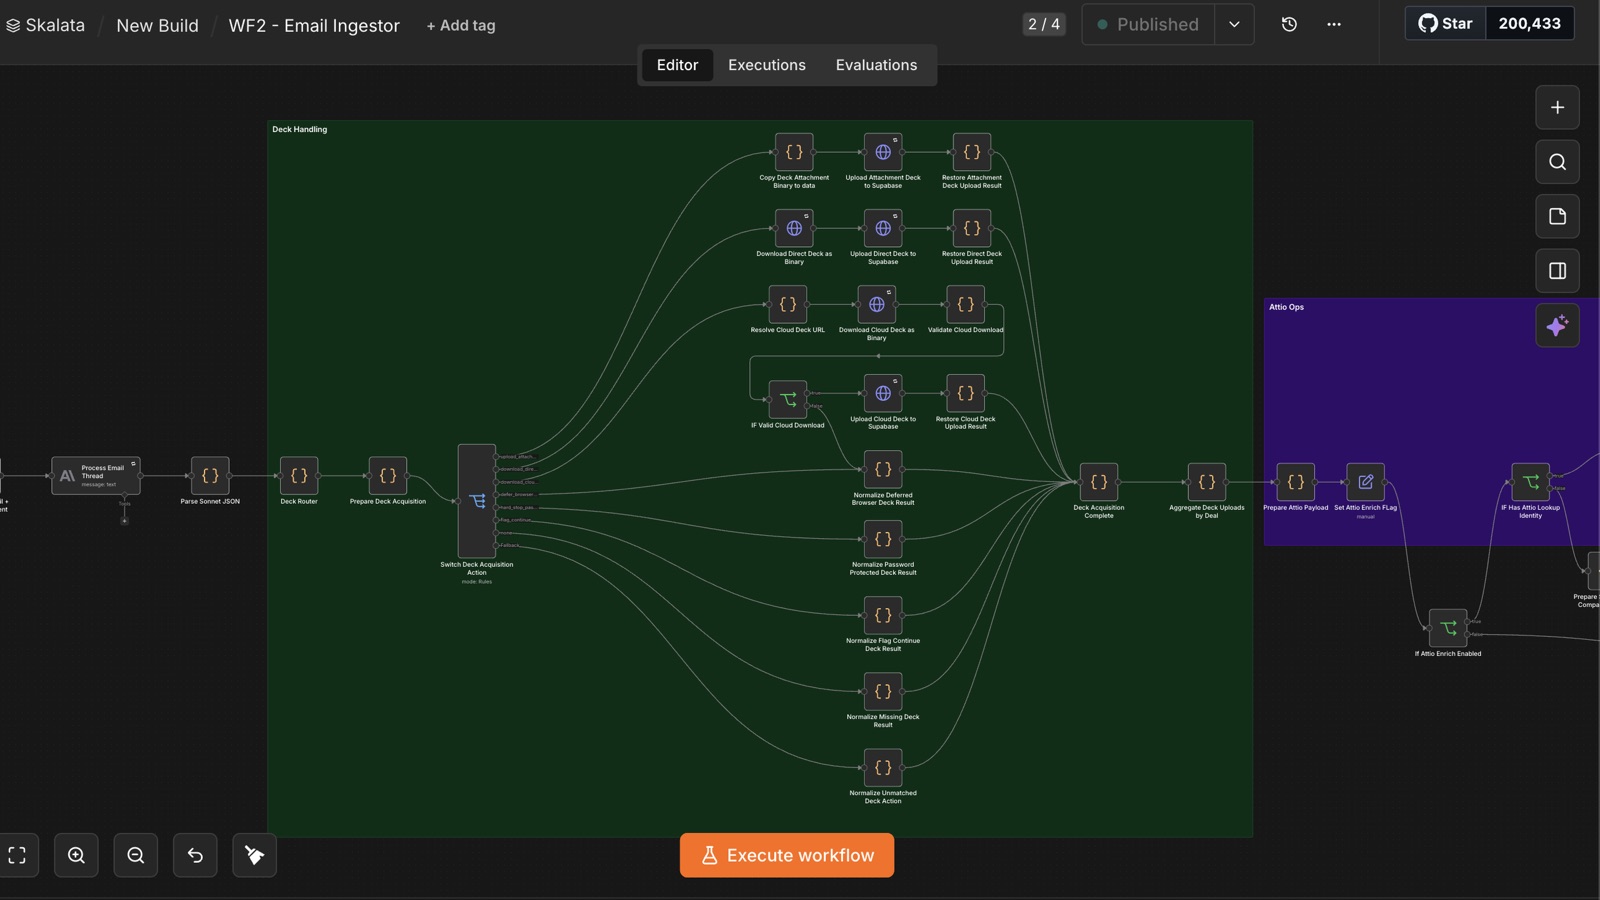
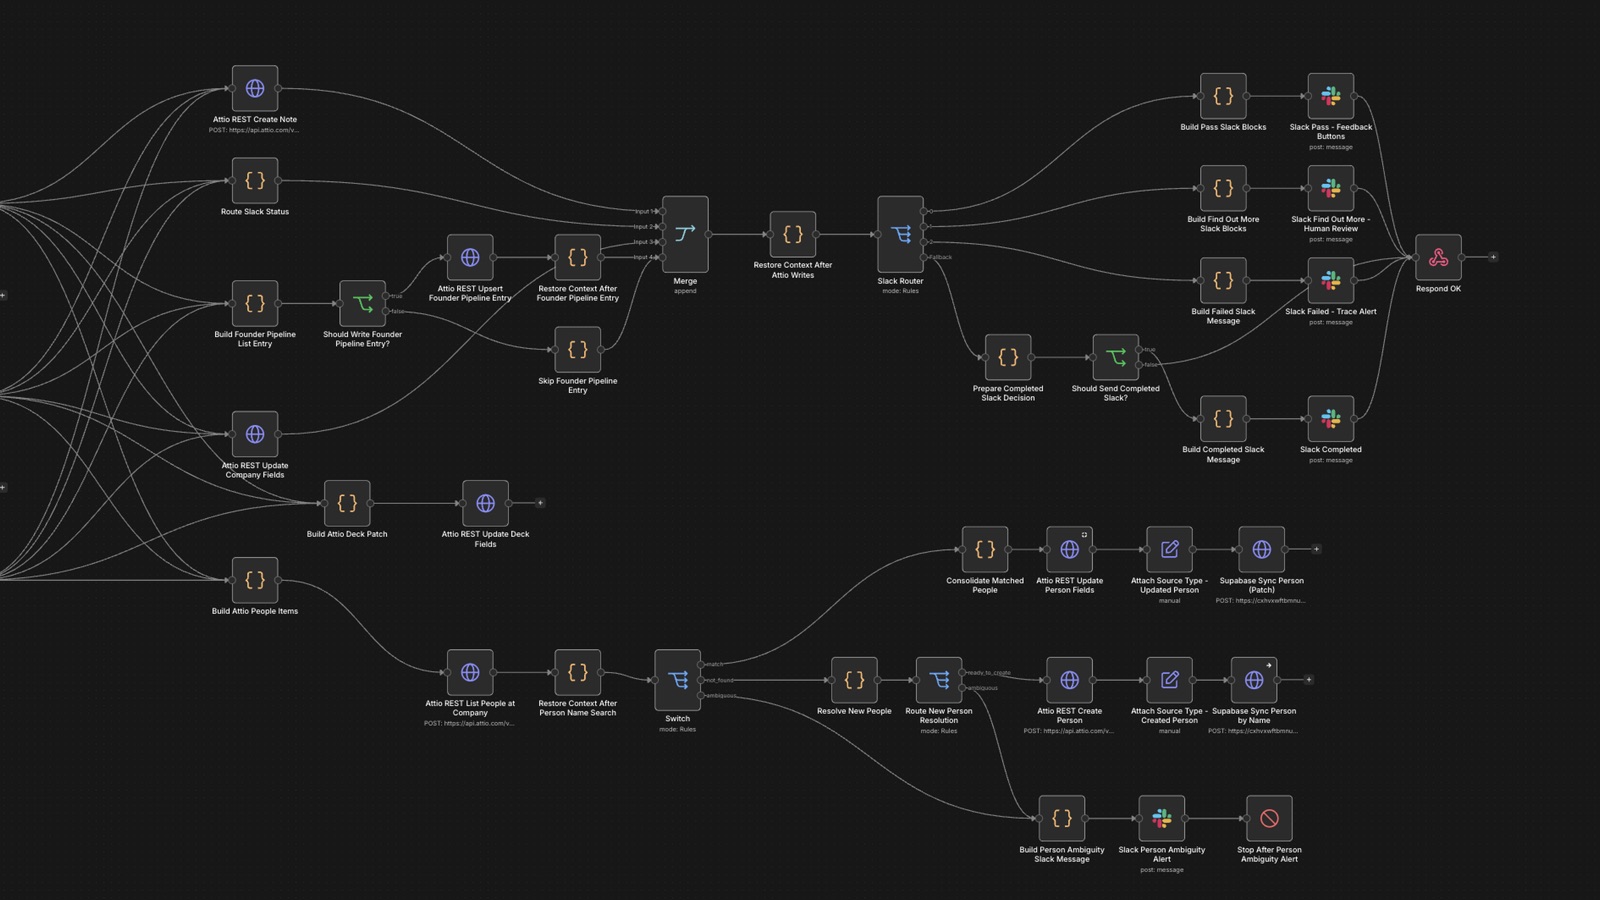
The email ingestor was by far the hardest to build, because every email arrives in a different shape. It might be a founder pitching their own company, a referral for one company, or a referral that mentions three. The deck might be attached, sitting behind a DocSend or Canva link, locked with a password, or missing altogether. Each of those needed its own handling before the AI could read anything.
The email ingestor in n8n. Each branch handles a different kind of deck: attached, linked, in the cloud, password-protected or missing.
2. It works out what the company is, and who's behind it
The AI reads the deck and website together and pulls out what the company does, its traction and funding, and who's on the team.
StackHow it’s built
LangGraph runs the stages in a fixed order. When a deal is re-analysed with new information, it re-runs only the stages the new information touches.
Doc Intelligence (Claude Sonnet) runs first. It uses Firecrawl, a tool that turns websites and files into plain text, to pull the text off the deck and the website, then picks out the founders' names and any competitors the deck mentions. Competitive Intel does its own research, so those competitors are only a starting point.
3. A gate checks fit, a human checks the gate
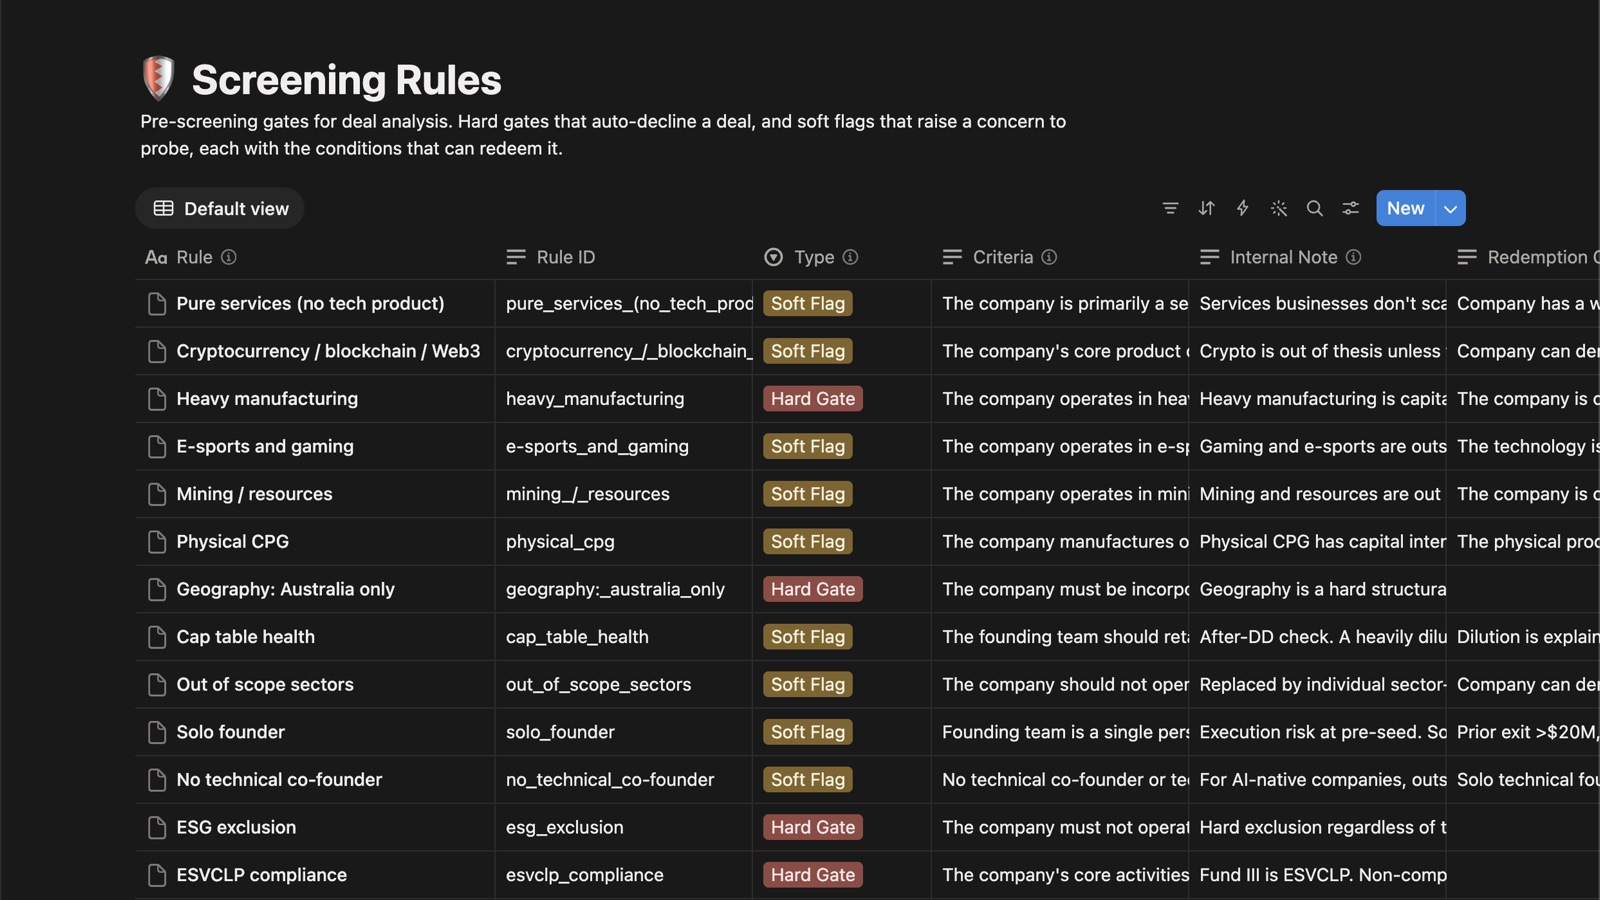
Before the expensive work runs, a gate checks whether the deal is even ours. It looks at the stage, the kind of company, where it's based, and whether the fund can back it at all. Some of these checks are hard rules that can end a deal, but the AI never turns a deal down on its own. A partner confirms every rejection, because a rule will sometimes turn down a deal we'd want to see, like the founder in the next paragraph.
Geography is the clearest case. Our mandate is Australian companies only. Part of that is ESVCLP, the scheme that gives our investors their tax benefits, which generally needs at least half of a company's assets and half of its employees in Australia. So location is a hard gate. But every so often an exceptional founder based overseas lands in the inbox, and we still want the option to look. You build the gate for the ninety-nine per cent and leave a human to catch the one, because the exceptions are too varied to encode. A raise or a valuation well above our usual range trips a hard rule too, and we'd be lying if we said a round everyone's chasing never made us want a closer look.
StackHow it’s built
The gate runs on Claude Sonnet. It checks the hard rules (stage, type of company, geography, and fit with the fund's mandate) and looks for softer warning signs.
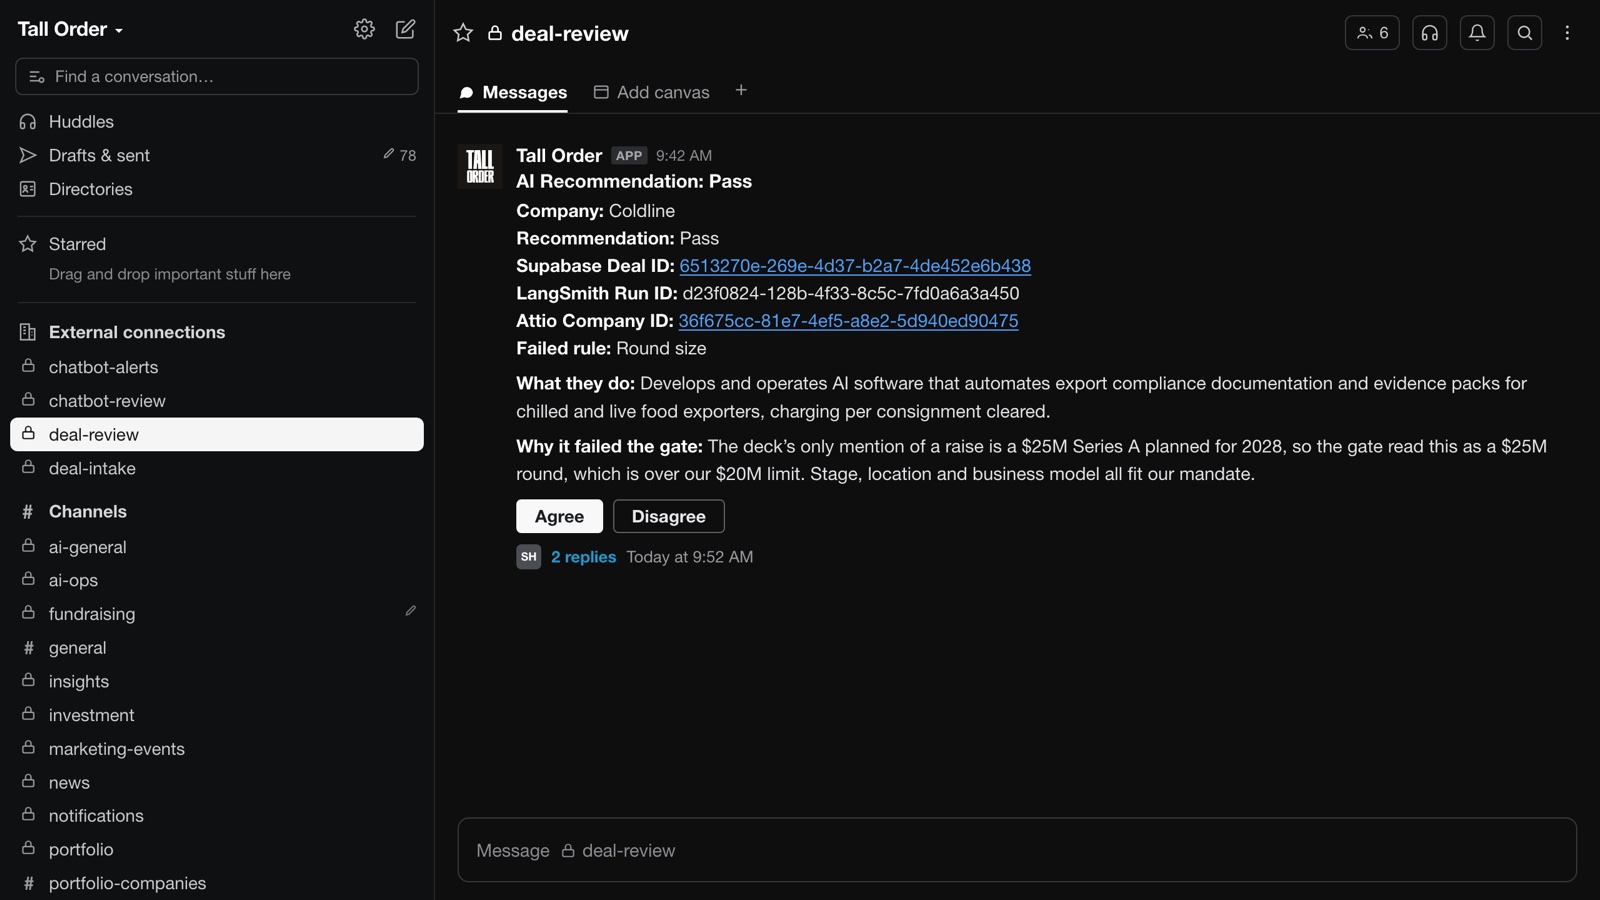
If a hard rule fails, the rejection goes to Slack, where a partner agrees or disagrees before it's final.
A warning sign doesn't stop the deal. It becomes a question for the founder.
If nothing fails, the research agents start on their own.
Every decline is recorded in Attio, our CRM.
A recommended pass lands in Slack for a partner to agree or disagree. Shown with Coldline, our made-up test company.
4. The deep work runs
If nothing fails, the heavy research runs, several agents at once where they don't depend on each other. One builds the founders' full history. One sizes the market itself and tests the deck's numbers against it. One looks up the competitors selling a similar product to the same kind of buyer. One finds the founders' contact details.
StackHow it’s built
The research agents run on Sonnet. Founder Intel and Market Trends run at the same time, and Competitive Intel waits for the market work.
Founder Intel builds each founder's work history from Renidly, a LinkedIn data provider, and web search.
Market Trends sizes the market with Perplexity or Exa, two AI search tools we're testing side by side.
Competitive Intel searches the web for competitors and what they've raised, across Crunchbase profiles, recent funding rounds, YC-backed companies and press coverage. It matches them on what a company sells and who pays for it, so a satellite maker gets compared with other satellite makers, not with every software firm selling into the space industry.
Enrichment finds the founders' contact details through FullEnrich, which tries several data providers in turn and stops at the first good answer.
5. It writes the memo, then checks it
Everything above goes into the one thing a partner reads, the memo. It has the investment overview, the main metrics, a rating on each of our 30 criteria, rolled up into six dimensions, the red flags (possible deal-breakers) and soft flags (things to check), a recommendation (Proceed, Pass or More Info), and an interview agenda with the sharpest questions to put to the founder.
The memo compares the company with real past deals, with citations, not with whatever a partner happened to see last week. Those past deals were in the database from day one, because the cohorts from the accelerator we used to run and the deals we'd already written up went in before the first live deal ran. Then a second agent checks the draft against every source and flags anything the sources don't support, before a partner sees it.
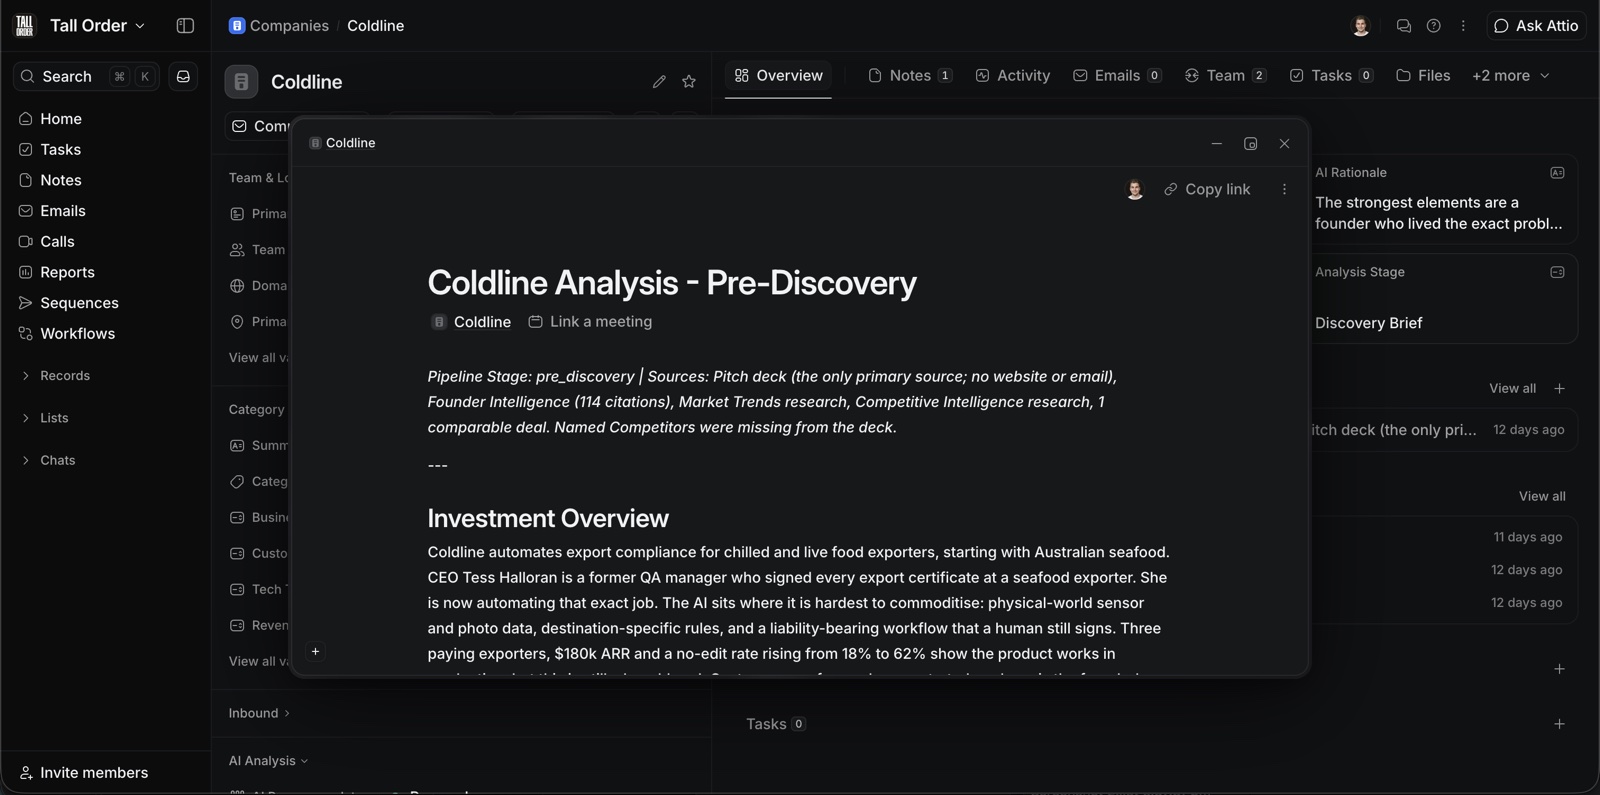
The memo, written straight into the company’s record in Attio. Shown with Coldline, our made-up test company.StackHow it’s built
Synthesis A (Claude Opus) reads everything the earlier stages produced and drafts the memo.
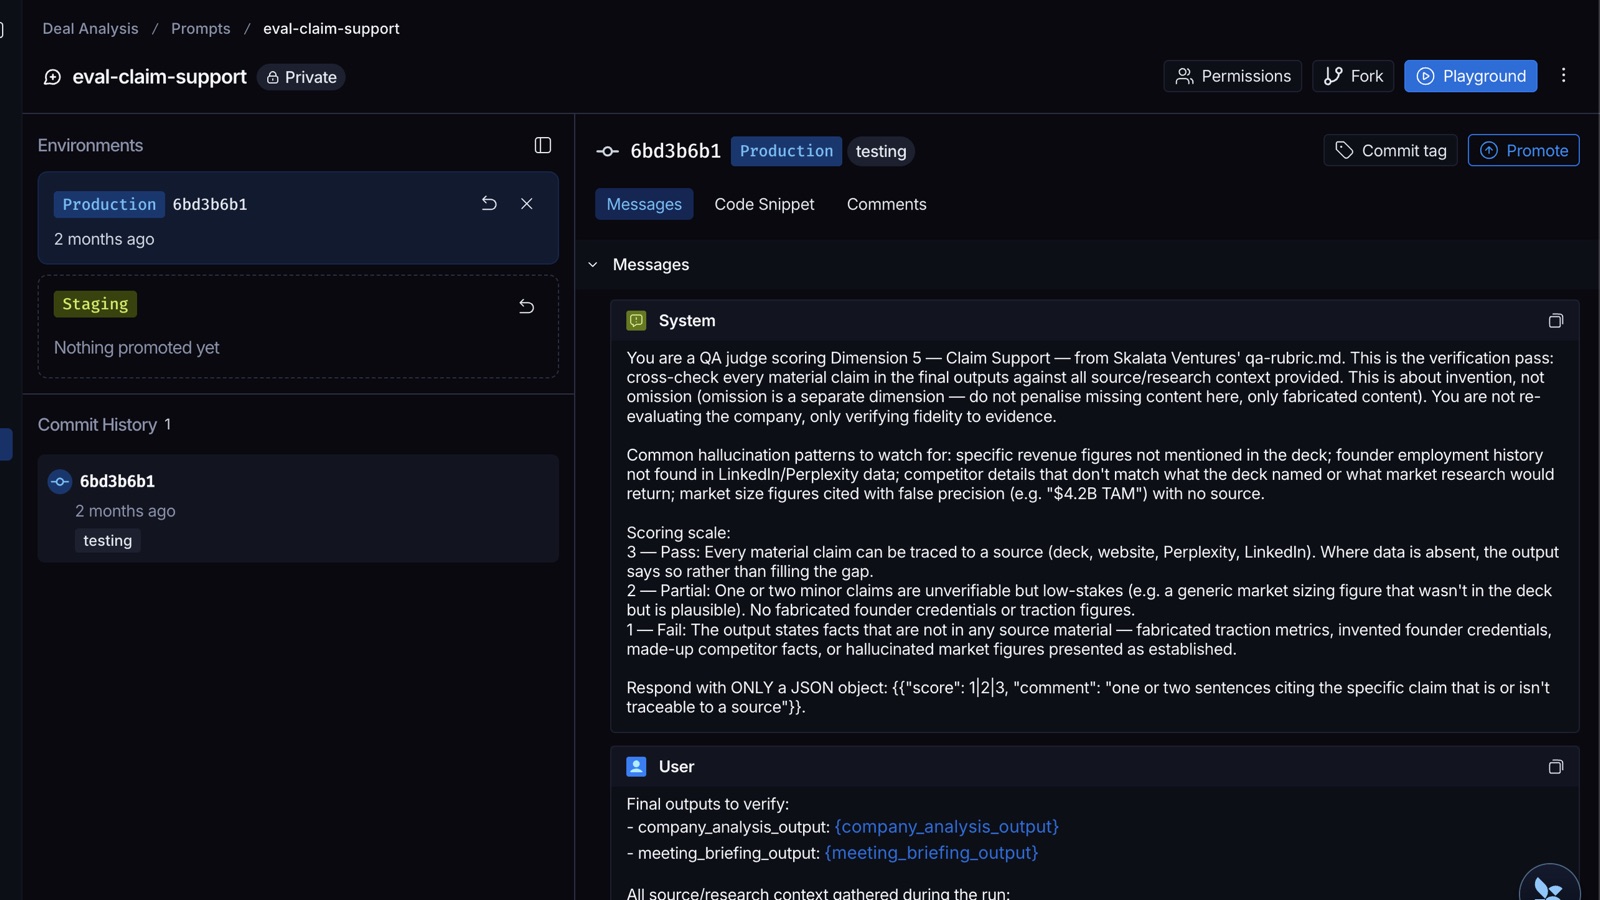
Synthesis B (Claude Opus) checks that draft against the original documents and every agent's output, and flags any claim the sources don't support before the memo is saved.
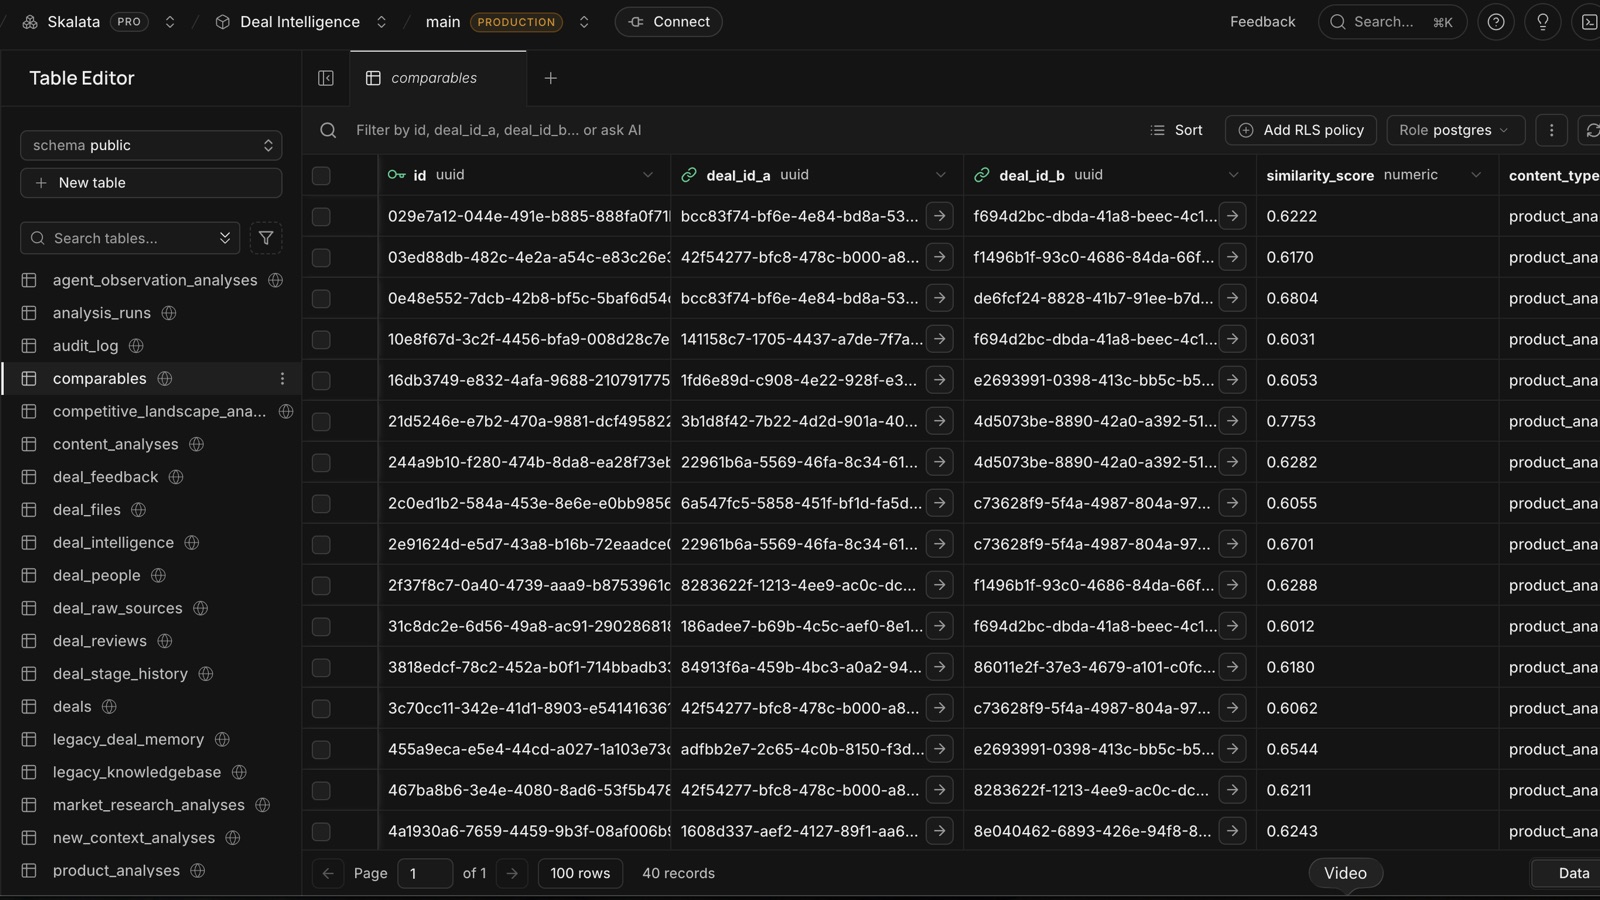
Comparables come from Supabase, our database, where every finished analysis is stored as a set of numbers describing the company (that's what pgvector does, which we could not have told you in 2023).
The AI's memory. Every analysis stored in a database we own, and the most similar past deals pulled out as comparables.
6. An AI committee built to disagree
In an investment committee the outlier view gets talked down to the median one, and at seed the outlier is often the deal. So an AI committee argues every deal from four opposed positions, some modelled on the reasoning of investors we respect. The sceptic hunts for the reason to pass, which every investment committee already has a person for. The optimist looks for the asymmetric upside. The futurist asks where the world goes if it works. The operator checks whether it can be built. Together they report where they agree, where they still disagree, and what to do next. The partner sees the strongest case for and against before deciding.
StackHow it’s built
The debate runs in LangGraph. Each of the four personas is its own agent with its own instructions, and all four run on the same model.
Every live agent, the AI committee included, is listed on AI Ops.
7. A human makes the call
The AI makes a recommendation and lays out the evidence. It never decides whether to back a founder. A partner does, with their name on it, because a partner has something to lose if it goes wrong and software doesn't. There's no "the AI flagged it" to hide behind here.
Four things no model touches.
Finding the founder before they're findable. The best founders often aren't in any database yet. Even once software does the searching, a person decides who's worth chasing.
Reading the room. A deck can be polished, but a person across a table for an hour is harder to stage.
The left-field question. The AI asks every sensible question. The question that changes a decision is usually an odd one that only occurs to a partner in the room.
Backing them, and being picked by them. A founder picks one investor over another because of conviction, a reputation staked on them, and a relationship built over years.
StackHow it’s built
When the analysis finishes, the memo and a confidence score go into the company's record in Attio. The memo comes in two parts, a Company Profile and Briefing Notes, and every earlier draft is kept. Every output and file is saved to Supabase, and a message goes to Slack. Re-analysis, and the jobs that run when a deal moves to the next stage of our pipeline, are separate workflows.
How it's built
The four layers
n8n moves the data, LangGraph runs the agents, LangSmith manages and monitors them, and Claude thinks. Keeping them separate means we can swap any one out without rebuilding the rest.
n8n, a workflow automation tool, takes each deal in, puts it into one standard format, and writes the results out to every other system we use.
LangGraph runs the stages in a fixed order and saves its progress as it goes, so a run can stop for a partner and carry on.
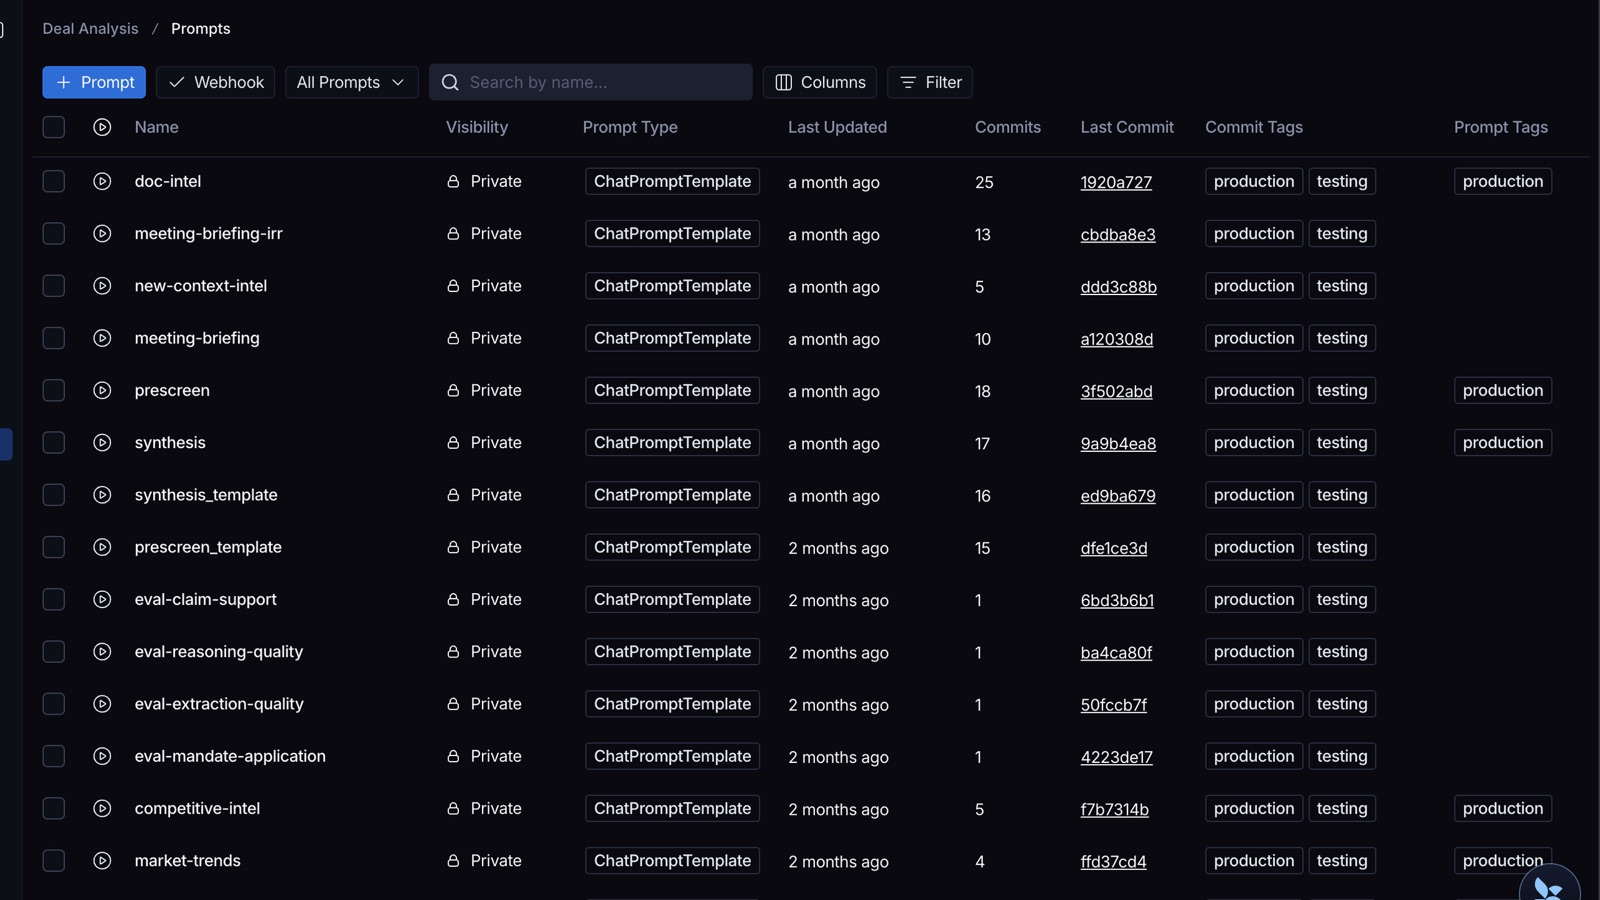
LangSmith holds every prompt, with each version saved, logs every run step by step with its cost, and tests every change before it goes live.
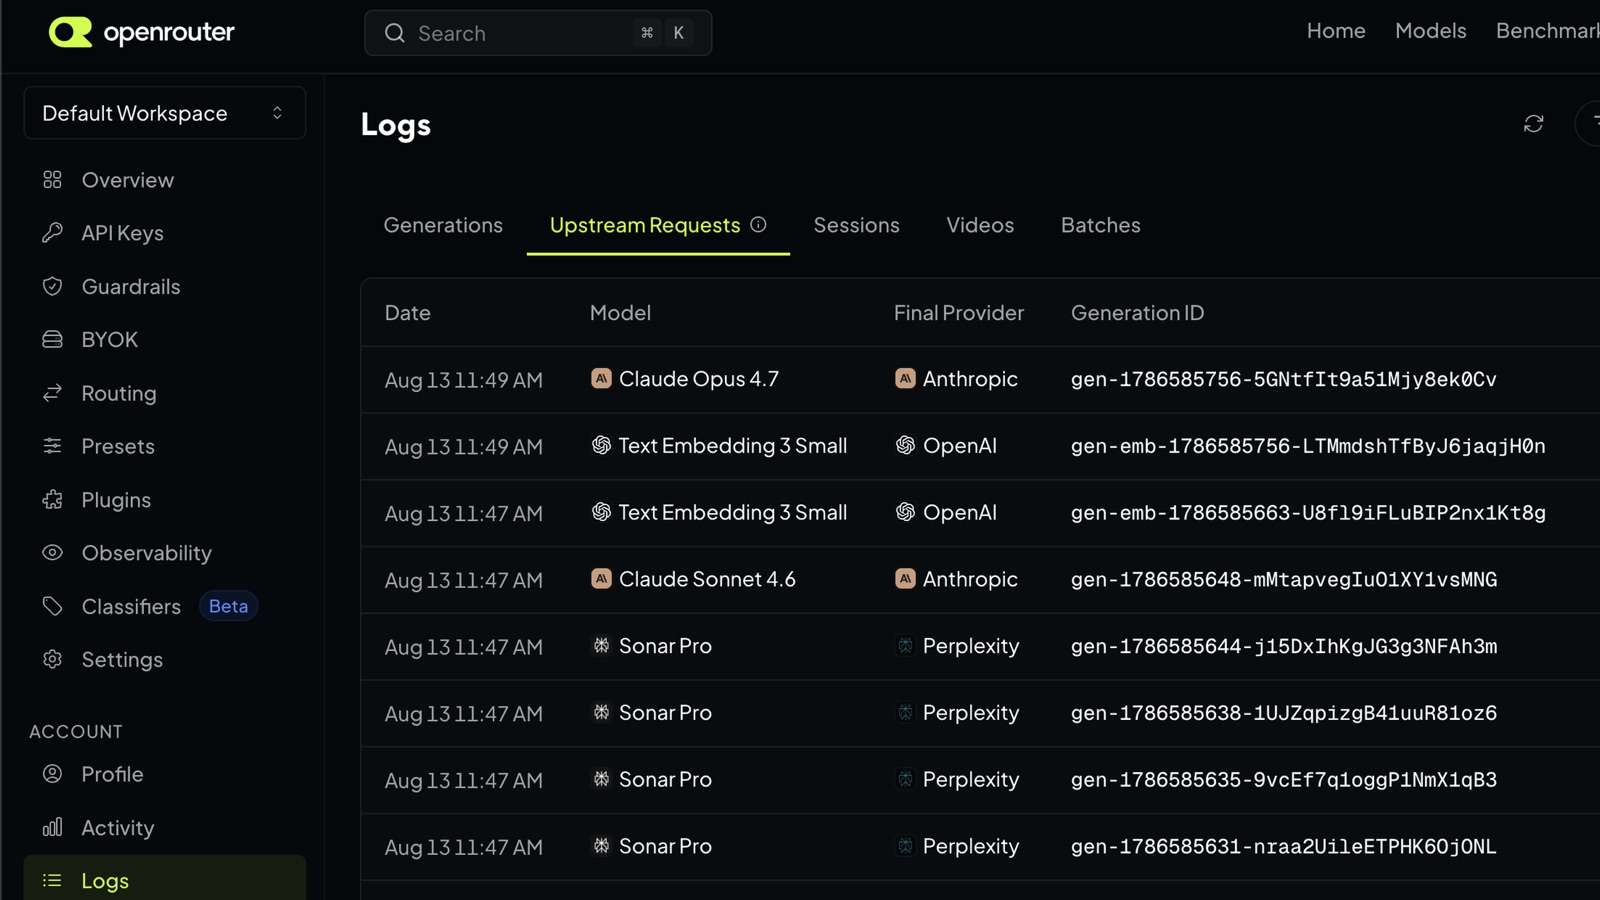
Claude does the thinking, reached through OpenRouter, a service that connects to every major model provider, with Opus and Sonnet on different jobs.
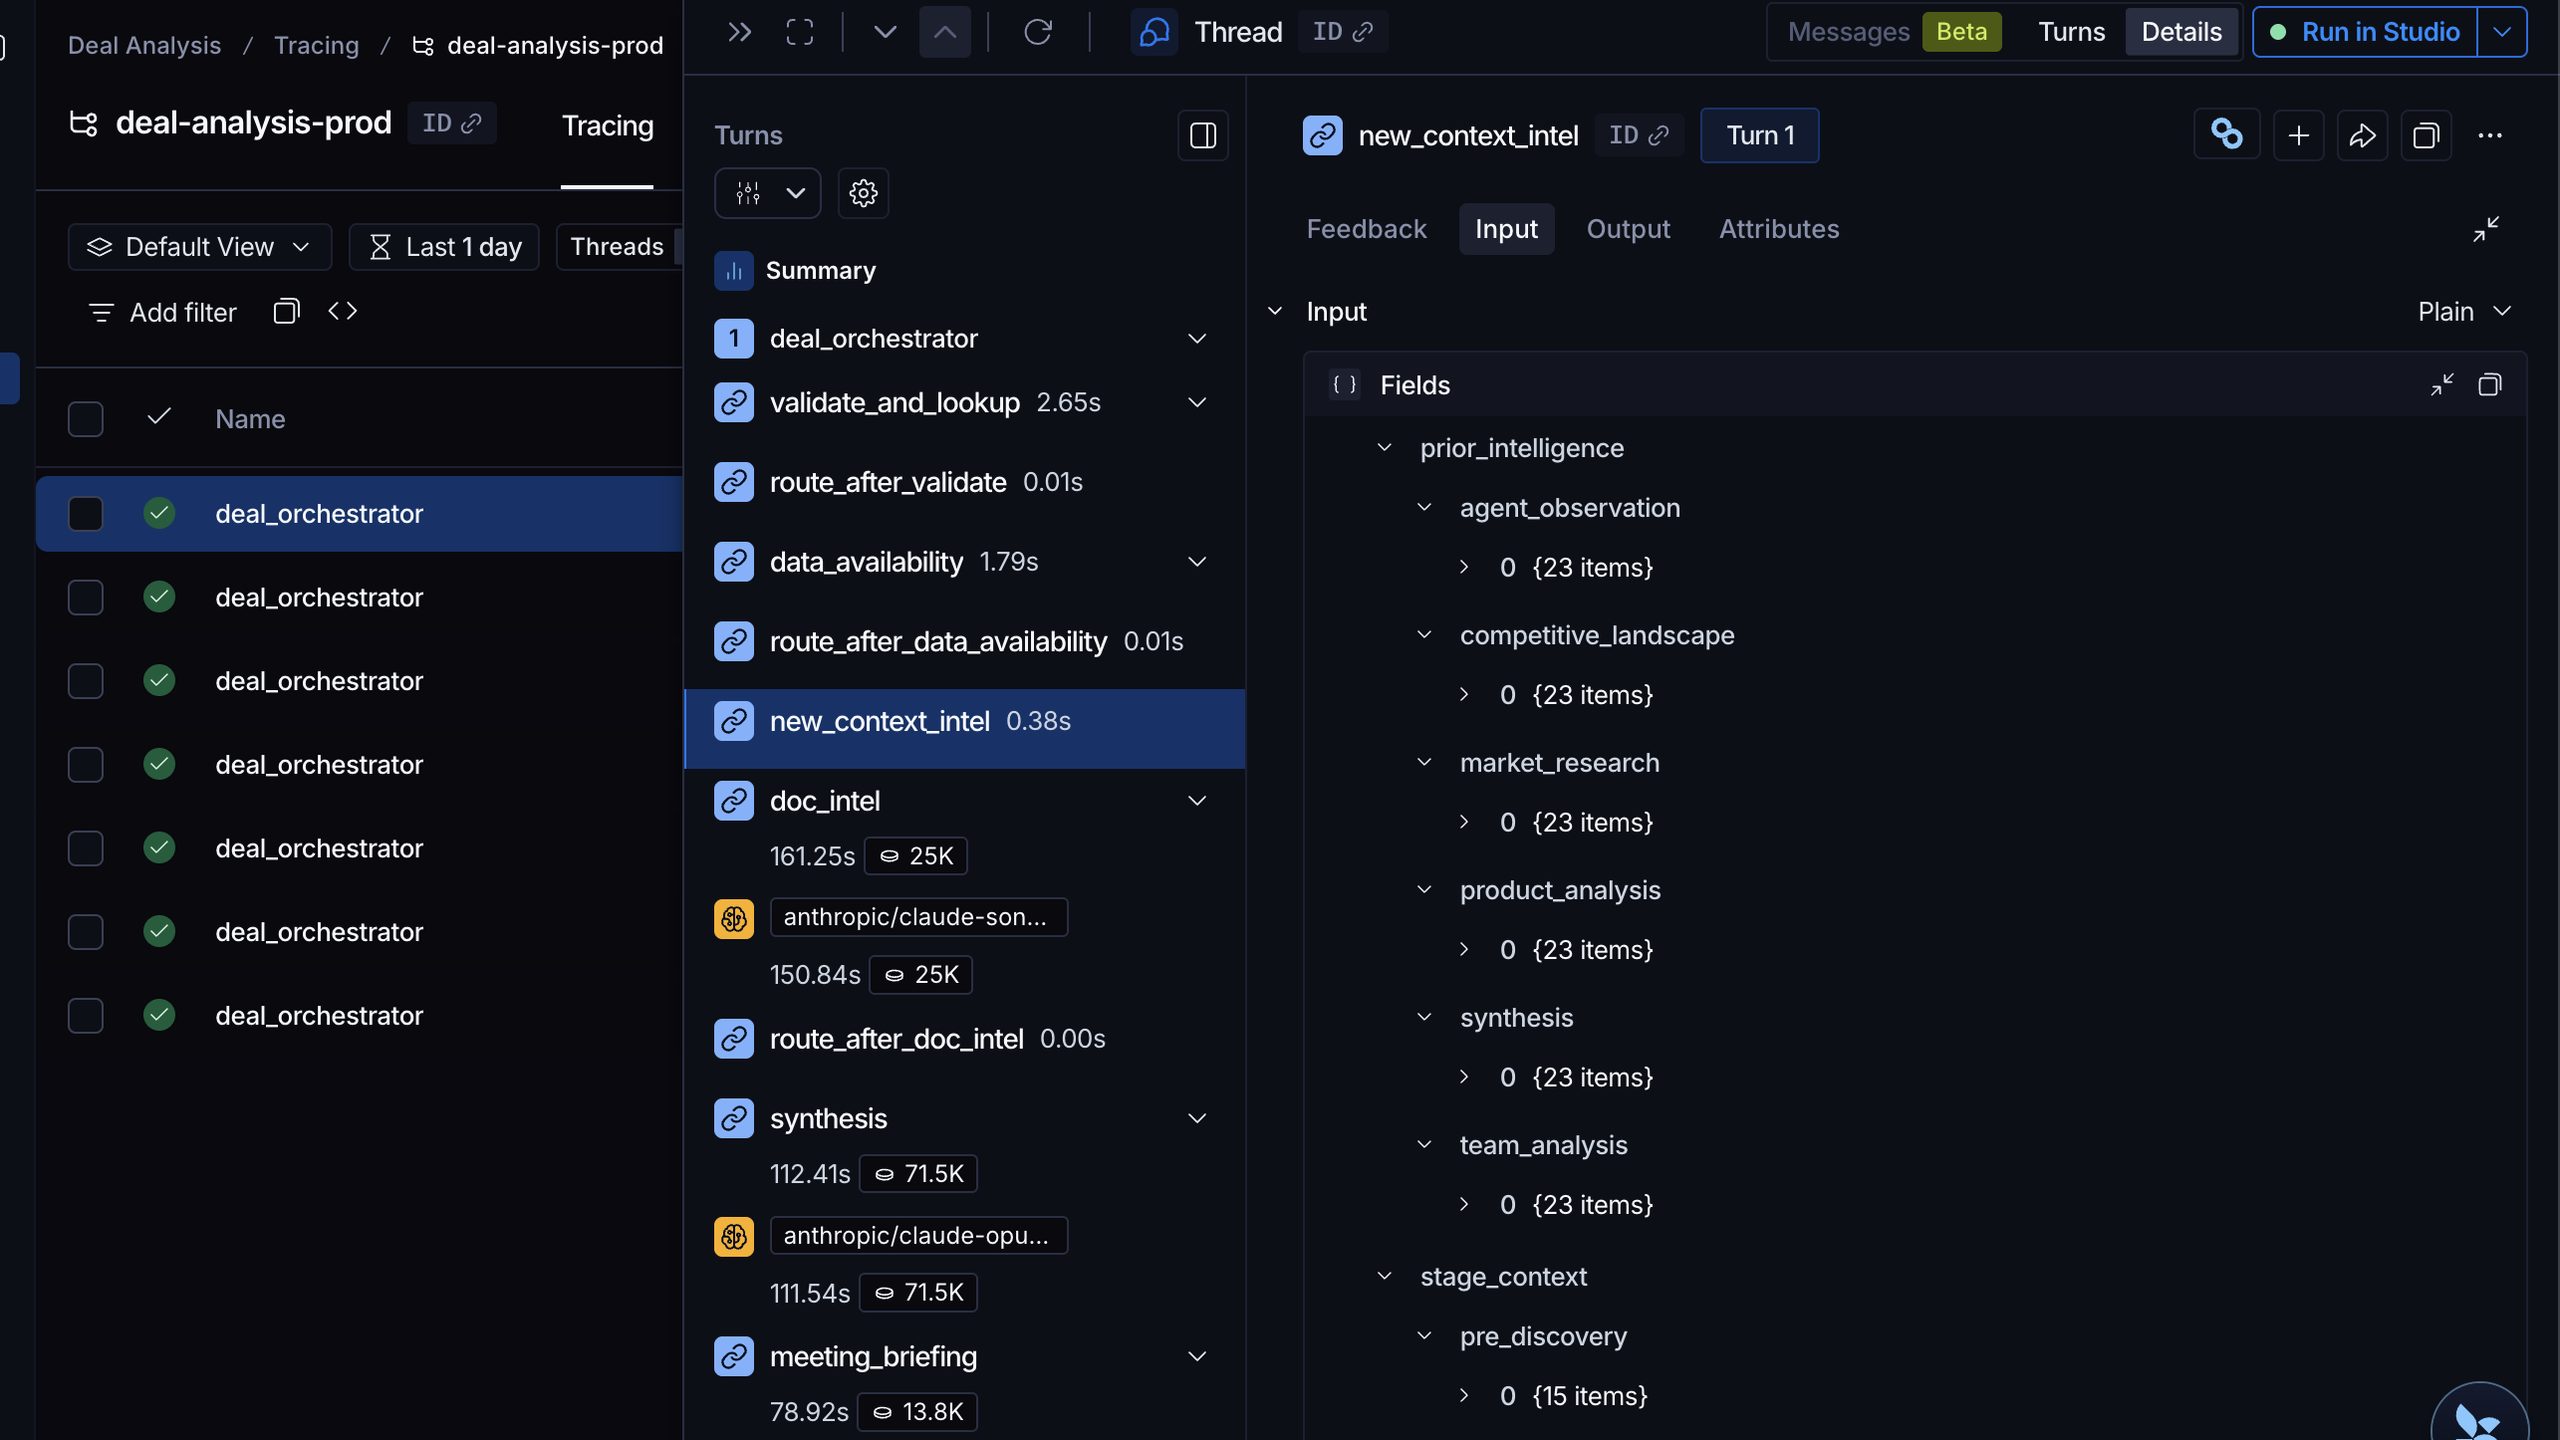
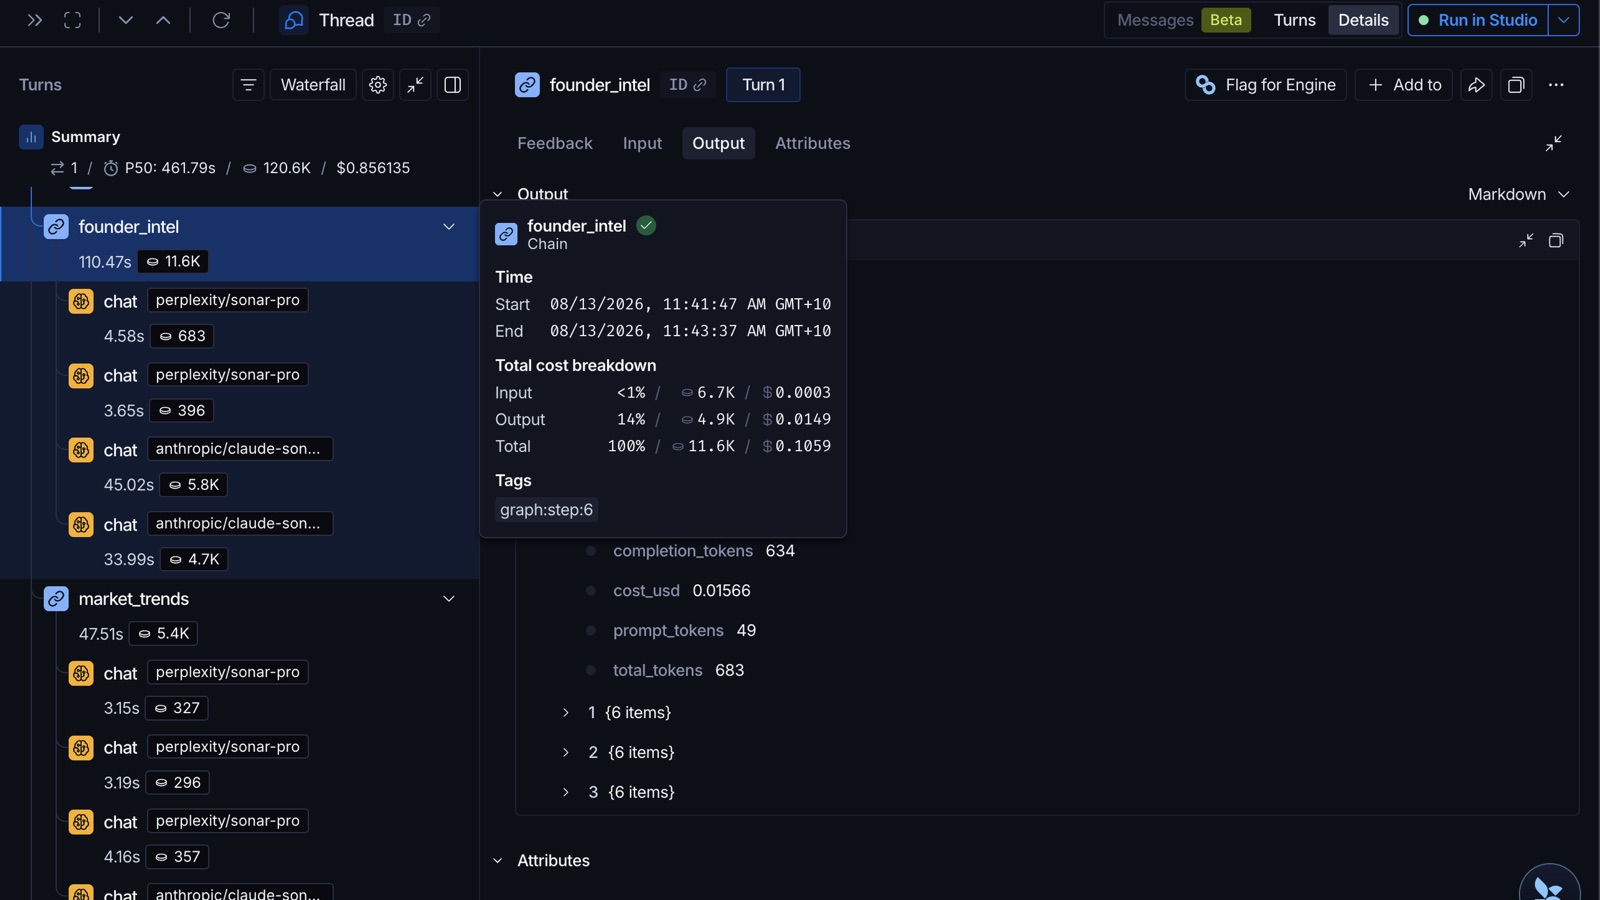
n8n, which takes deals in and writes the results out.One run in LangSmith. Each stage in order, with the time it took and the tokens it used.
What we built, and what we bought
This wasn't our first foray into AI ops by any means. Since March 2023, when GPT-4 launched, we'd been running one n8n megaworkflow™ with basic research agents against our investment mandate. Pretty ugly, but it worked, and it screened real deals the whole time. By the time we rebuilt, it had hit thousands of edge cases from live deals, and we'd made our first crude attempts at writing the mandate down for a model.
We looked at two kinds of product first. The VC products (Kruncher, and the new ones shipping almost daily) let you set your own criteria, but the pipeline underneath is theirs, and we change ours every week. Agent platforms like Relevance AI, Gumloop and Lindy let you build your own, but they decide how the agents are wired and don't show you why a run did what it did. Those are the two things we need to control.
Twice we had to decide whether to build something ourselves or use a tool that already existed.
We built our own deal dashboard, got as far as a working prototype, and killed it, because logins, permissions, a record of who changed what and somebody owning the thing for the life of the fund were most of the work.
The second time was the system that analyses each deal. We could have built all of it ourselves, including a connection to every system we touch, a way to pause a run for a partner and resume it exactly where it stopped, and a record of each run we could read. We'd have spent most of the rebuild on those and ended up with worse versions, so we built the analysis on the tools above.
The usual objection to n8n is that it's a tool for people who can't code, and a canvas turns into spaghetti once the logic gets real. Fair, and at the start that was us. That's why none of the analysis happens there.
We use it to pick up deals and write results out, which is mostly logging in to other systems, retrying when something fails, and slowing down when a service asks. All of that comes ready-made. None of us had built anything like this before, and watching a run move step by step through the canvas taught us more about what we'd built than any log. (That argument has an expiry date, and we know it.)
So we own anything that holds what we believe, and rent anything that's already solved. The rubric (the criteria we score every deal against) and the order the stages run in are ours, because they're what we keep changing. The connections to other systems, saving a run's progress, the run logs and the CRM never will be.
Anything a partner has to use lives in a tool they already have open: the criteria in Notion, decisions in Slack, the deal record in Attio. If a partner has to remember to open a separate tool, they stop opening it.
Why the agents run in a fixed order
Most of what's written about agents right now assumes you hand a model a goal and a bag of tools and let it work out the steps for itself. We tried that first.
We had an orchestrator agent handing work out to sub-agents. But each one only saw whatever the orchestrator passed on, and the orchestrator only saw the summaries they sent back, so a lot got lost in both directions. If you try to fix that by sending every agent everything, each one's context window (how much it can read at once) explodes, and models get worse the more you give them to read. Chroma, which makes a database for AI apps, tested 18 of them and found exactly that, even on simple tasks. Cognition, who make the coding agent Devin, found the same thing. Sub-agents that can't see each other's work make choices that don't fit together. They've since got a version working, and still say passing context between agents is the hard part.
So we decided linear and deterministic was fine here, which, you know, is a lot less exciting to post about. Everything's "agentic" at the moment. Ours has about as much agency as a Melbourne tram. It goes where the tracks go, and that's pretty much what we wanted. The agents run one after another in an order written into the code, and the model just makes the calls inside each step. The only fork is the gate, which decides whether a deal goes on to research.
If you look into it, Anthropic say something pretty similar. Their advice is to let code set the path and only hand the steps to the model when you need to. Dex Horthy, who runs HumanLayer, a company that builds tools for AI agents, reckons most products sold as agents are "mostly deterministic code, with LLM steps sprinkled in at just the right points". And Anthropic's own multi-agent research tool used about 15 times the tokens (the units models charge by) of a normal chat, which only pays off on work valuable enough to cover the bill.
If you're a developer, you're probably thinking there's a way round all of that, and you may be right. But we already knew what order the work goes in, so writing it down was easier. It's also cheaper, and runs come out more consistent.
It gets more agentic where nobody can write the steps down in advance. The research agents already choose their own searches, and the next jobs on the roadmap are the open-ended ones. The next version of Sourcing Signals will go looking for founders before they apply, from new company registrations, GitHub activity, patents and people leaving scale-ups. Deal tracking will keep watching deals we passed on and flag one when something changes. Neither job has a fixed set of steps, so that's where we'll let the agents decide what to do next.
Getting it out of our heads
The engineering was the "easy" bit. Everything above runs on criteria we had to write down ourselves, and that was the harder job by some distance.
Writing down what we believe
A fund runs on a thousand unwritten calls, i.e. what counts as too early, how much a thin market matters when the founder is exceptional, whether a second-time founder whose first company was a dumpster fire is a red flag or the best bet on the table. None of it was written down. It lived in the partners' heads, and you only heard it when they disagreed.
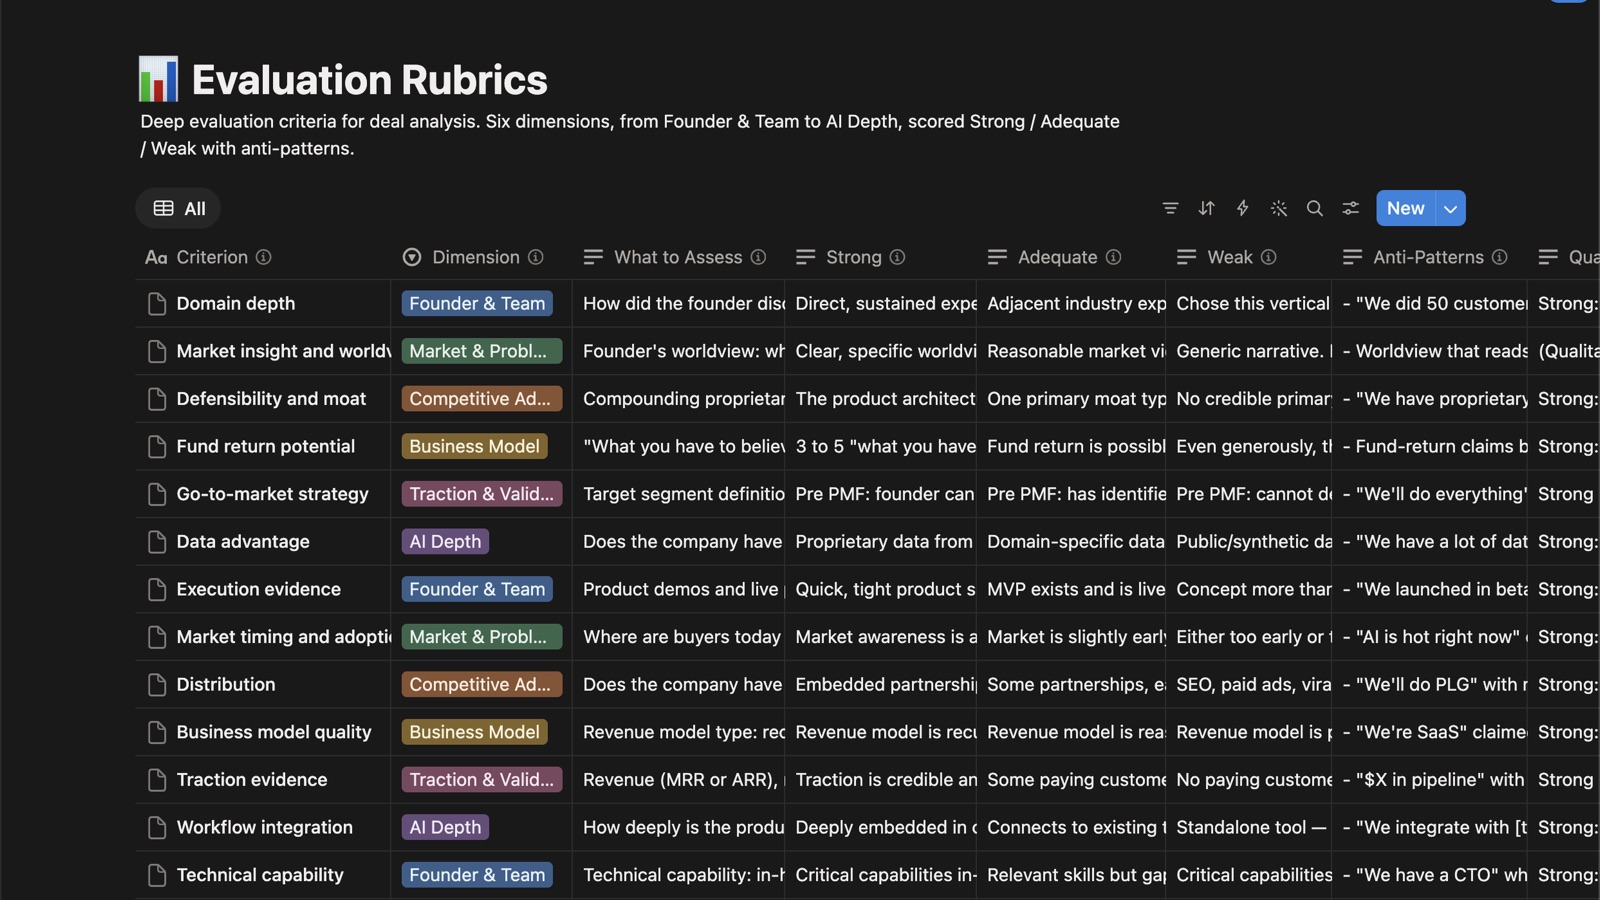
So we wrote down every criterion that matters, what strong, adequate and weak look like for each, and the impressive-sounding claims that shouldn't count. A slide full of enterprise logos is one of those claims. A board of well-known advisors who've never taken a call is another.
On every deal we write down what would have to be true for it to work. That's our thesis, and the AI's job is to find evidence for and against it without getting tired, bored or talked round.
One criterion asks whether a founder is a real insider. In a meeting that's a gut feel. Written down, it counts years spent on the problem and years operating in the industry, and gives credentials on paper less weight, so a polished deck can't make up for a thin track record. There are 30 criteria in all, each rolling up into one of six dimensions.
We argued over the second-time founder. Some of us had backed exactly that founder and watched it work. Some had watched the same profile make the same mistake twice. In the end, a founder who can tell you precisely what they got wrong scores well. A founder with a tidy explanation of why it wasn't their fault doesn't. It's now a criterion. (Singular. We say it in meetings now, and we're not proud of it.)
Then a model has to apply each criterion the way we meant it. We wrote what we thought was a clear rule on domain depth. It came back rating a founder highly for eight years in an industry, when those eight years were spent selling for a company near the problem, not working on it. Our rule said time in industry. We meant time on the problem. We reworded it, re-ran it over twenty past deals, and found the change had moved scores somewhere else. Getting it right took weeks of that.
Each criterion scores strong, adequate or weak, and then we subtract points for the things that worry us: a solo founder, no revenue yet, a crowded market, a valuation ahead of the stage.
Criteria scored Strong, Adequate or Weak, with the impressive-sounding claims a polished deck shouldn't score on.
Rules like these need data, and most of it isn't public. It's easy to find out what a Series A company looked like on the day a fund invested, because the memos get published and the metrics end up in the announcement. Almost nobody can see what a company looked like at pre-seed, on the day someone backed it with nothing much to measure.
We can, because we ran an accelerator ourselves, first with the Melbourne Accelerator Program and then with our own program at Skalata (RIP). For every cohort we had a long application form from everyone who applied, five months of monthly reporting from everyone we took, and our own people working alongside them the whole way. We know exactly what those companies looked like going in, and we know what happened to them afterwards. Every criterion is built on that history, and no data provider sells it.
The rubric is a decade of seed judgement written down. We could replace every tool named in this piece next year and still have it.
Hard gates and soft flags, each with the conditions that can redeem it.
Writing it down forced arguments we'd avoided for years, and those arguments were the most useful part of the whole exercise. Then every belief had to hold up against our own past deals.
Nobody had marked up past deals the way we wanted the AI to read them, so Shahirah Gardner (Shah), one of our Venture Partners, did it by hand. She wrote up hundreds of past deals, put each one next to the AI's version, and marked every line where they differed. It took weeks, and until it was done no automated score meant anything.
StackHow it’s built
The rules sit in two linked Notion databases.
Screening Rules holds the hard gates and the softer warning signs.
Evaluation Rubrics holds the 30 criteria. Each one has what strong, adequate and weak look like, the claims that shouldn't count, and cut-off numbers we keep private.
Partners edit both in Notion. Whalesync, a syncing tool, copies them into Supabase along with our portfolio database, and the AI reads them from there on every run. A rule only reaches the AI once it's marked Live.
You can't outsource the understanding
Freelance developers helped build the system, and that part you can hand over. The understanding underneath it you can't. It takes years inside a firm to absorb, and it only comes out when you're forced to write it down one decision at a time, which can't be project-managed between board meetings. So a VC had to drive. We're not AI engineers, as the first fifty pages of our plan made clear. We know seed investing, and we wrote the rules ourselves.
This is why selling "AI automation" has become the new dropshipping, the AI-era snake-oil guru pitch. If you don't understand a business from the inside, walking in and automating it is bloody hard, and you usually end up with something Zapier could have done ten years ago. Point an agency with no domain depth at a problem like ours and you get a polished system that automates a generic version of the job. At that point you may as well just buy Kruncher.
How we keep it honest
The same deal can come back slightly differently on two runs, so we need to see inside the system. Otherwise nobody can tell why it did what it did, notice it getting worse, or improve it on purpose. We made two decisions to avoid that. First, we kept the data handling apart from the analysis, so a result that fails to save never looks like a bad analysis. Second, we use LangSmith to record every run and block any change that doesn't do better on a fixed set of tests.
Checking every claim
The system assumes founders round up and models make things up, so it checks the deck against its own research, tags every claim with its source, and has a second agent check the memo before a partner sees it. How we got there.
The judge that checks every material claim against its sources. A change that scores worse here doesn't ship.
The last risk is ours. A clean, confident score is easy to nod along to. So a partner never gets a single number. They get the bull case and the bear case side by side, a source on every claim, and their own name on the decision, which is a very effective cure for nodding along.
We can see why it did what it did
Every run is logged in LangSmith as one tree, with each prompt, tool call and cost sitting under the deal it belongs to, so when an output is wrong, we can find the prompt that caused it in a couple of clicks.
One deal's run in LangSmith, with every step and what it cost.
How we test every change
Nothing ships on a hunch. Every change is tested against Shah's marked-up set of past deals. A new prompt or a new model runs across the same past deals as the live version, and four AI judges score the outputs. They check whether every claim is supported by its sources, how sound the reasoning is, what was pulled out of the deck, and how the mandate was applied. Exact checks cover anything with a single right answer. If the change does worse on any group of deals, it doesn't ship, even when the average goes up.
We learned that rule the hard way. A tweak that sharpened the founder analysis made the market sizing worse, and we went a week before anyone noticed, including the person who made the tweak.
The set now covers thousands of past deals, and it grows with every deal we score.
Every prompt is versioned in LangSmith and loaded when a run starts.
Which models, and why
We use two Claude models. Opus 5.5 is Anthropic's top-tier model. It's the strongest at long-context reasoning and the most expensive per token, so we only use it for writing the memo and checking it. Those two steps have to reason across every source and every agent's output at once. Sonnet 5.5, the mid-tier model, is faster and cheaper, and handles everything else: reading the deck, running the gate and doing the research. We tried Haiku, the smallest and cheapest, on those steps too. It made too many mistakes to be worth the small saving.
People ask why we pay Anthropic's prices at all (let alone the OpenRouter tax!). We're not tied to any one model. Every call goes through OpenRouter, so changing model is a settings change, and we compare performance and cost against the alternatives as new models come out. During initial testing we ran the same deals through GPT, Gemini, DeepSeek and Qwen as well as Claude, and the results were very similar, because the rubric does most of the work. Claude is what we run today, and we'll move as soon as another model does better on our test set for the money.
When we change them
A new frontier model comes out every few weeks, and switching means re-testing the whole system. We only switch when a new model does better on our own deals by enough to cover any extra cost.
In early September we tested the newest Claude models. Per token, input and output, they cost about 15 per cent more. But they reason for longer before they answer, and that reasoning is billed as output tokens, so the cost of a whole deal went up more than 55 per cent. The results were about the same, so we stayed where we were. In early October we moved to Sonnet 5.5 and Opus 5.5, skipping two generations of Opus, because they did better on our test set. The memos are now shorter and more focused, and a deal costs about $1.50 to $2.
OpenRouter, the one connection we use to reach every model.
The AI handles the deal it was built to handle. The trouble is that a deal that returns a fund usually looks unlike anything it has seen. Take the market agent. It sizes the market itself and checks the deck's numbers against it. Point it at a company creating a category that doesn't exist yet and it finds no market data, because there isn't any, and flags a thin opportunity. On the AI's read, that's a decline. So was air mattresses for strangers. But "there's no market yet" is what the best seed bets look like, right up until they define the category. A model only knows what's happened before, so it scores anything unusual down. A partner who's seen the pattern can read the same thing as a reason to back it.
That's why a partner still reviews every deal the AI recommends passing on, and reads every memo before deciding whether to meet the founder. Finding the outlier the model marked down is the part of the job we kept for ourselves.
Other examples are the insider with no conventional CV, the metric that looks broken but isn't for this business model and the regulation that reads as a risk but keeps competitors out. There are thousands like them. We catch the ones we can and write new rules for them, and we'll never catch them all. We designed for this from the start. It's why every rejection goes to a partner, why the AI committee has an optimist and a futurist arguing against the sceptic, and why a partner makes every call. The AI is good on deals that look like ones we've seen before, and a partner reads the rest.
Every deal adds to what it compares against
The rubric was built on years of accelerator cohorts and portfolio companies, each watched from application form to outcome. What's new is the feedback loop. Every deal the AI analyses goes into the database the next one is compared against, logged with how it turned out: win, loss or pass. As our bets play out, we re-tune the scoring against what happened, and when a partner overrides the AI, we log who turned out right (so far, not always the partner).
The loop gets more useful with every deal, which is the reason to start early. A fund that began screening with AI last quarter can't buy our accelerator history, and can't skip the years it takes for outcomes to come in.
We'll rebuild it
We let it break. It obliges. An agent misreads a deck, a workflow falls over overnight, a model update shifts an output we'd spent weeks calibrating. The worst case is wasted compute and a re-run, because a partner still makes every call by hand.
None of this is finished either. The tools underneath keep overtaking each other every few months, and models that didn't exist when we started are already better at half these jobs, so we expect to replace most of it within six months.
Some of it isn't finished yet. Sourcing Signals, the agent that finds founders before they apply, is still in testing. Deeper technical and financial checks, for deals that get past a first meeting, are being scoped for early 2027. Alongside them we're building a deeper competitor review that goes beyond direct competitors to the other ways customers already solve the problem, and the risk that the model labs or the big cloud providers build the same thing.
What we keep through every rebuild is the rubric, the comparables and the tuning. The AI keeps no memory of its own, so all of that sits in our databases, not in the code. Every change gets an entry in the changelog.
AI OpsThis article covers our first build. Here’s how it runs today.